Data, Databases & ETL
SQL, data pipelines, ETL and analytics engineering
Introduction
In today’s data-driven world, organizations generate and store vast amounts of information daily. Managing this data effectively becomes a strategic necessity, powering decision-making, customer insights, and operational efficiency. The fields of data, databases, and Extract, Transform, Load (ETL) processes form the backbone of data management systems. They enable businesses to organize, process, and analyze data at a scale that supports growth and innovation.
This comprehensive guide explores the essential concepts, mechanisms, and practical applications of data, databases, and ETL. It aims to provide clarity on how these components work together and why their proper implementation can make a significant difference in a company’s ability to leverage data for competitive advantage.
Definition and core concepts
Data refers to raw facts and figures collected from various sources, which can be structured, semi-structured, or unstructured. Structured data appears in tabular formats like spreadsheets or relational databases with defined schemas. Semi-structured data includes formats like JSON or XML, offering flexibility in representation. Unstructured data encompasses text, images, videos, and other formats that lack a predefined structure.
Databases are organized collections of data stored electronically, designed to facilitate efficient data retrieval and manipulation. Relational databases, such as MySQL or PostgreSQL, store data across tables linked by relationships. NoSQL databases, like MongoDB or Cassandra, handle semi-structured or unstructured data better and offer scalability for large datasets. The core concept behind databases is to provide structured storage with query languages enabling users to perform complex searches and operations.
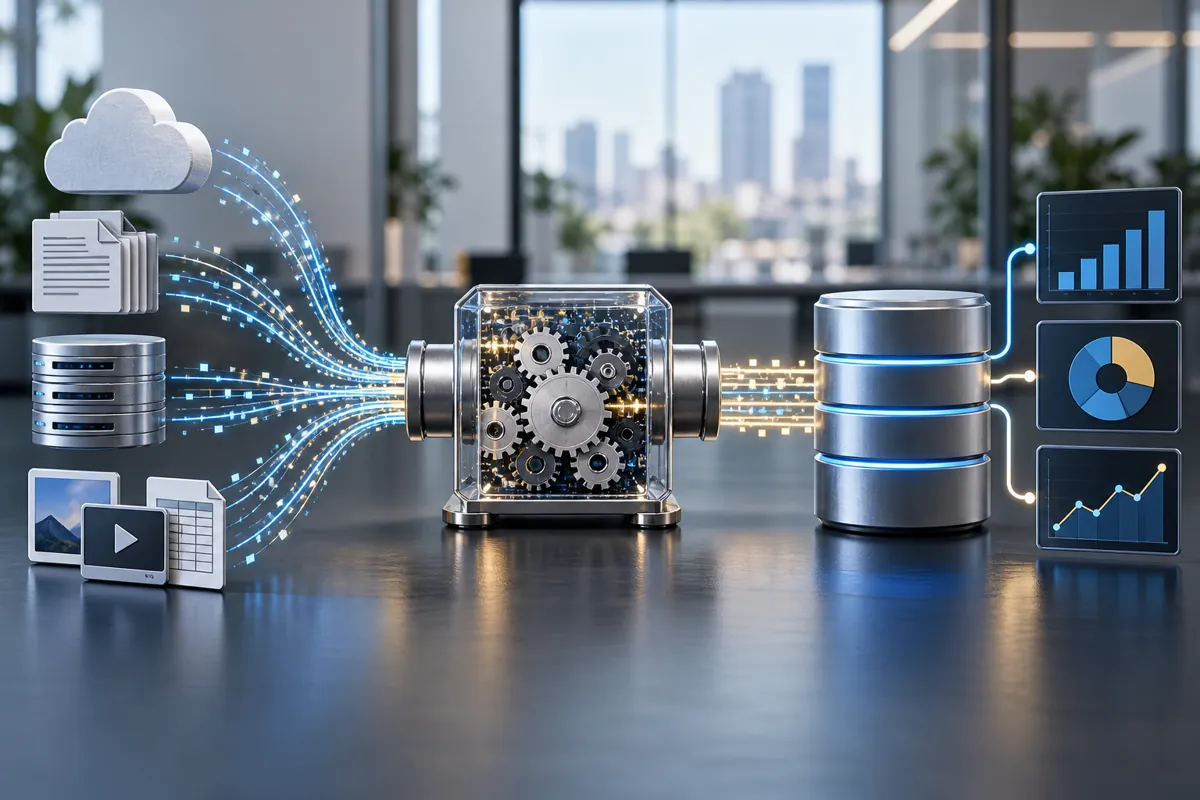
ETL stands for Extract, Transform, Load. It is a process that moves data from source systems into data warehouses or data lakes. Extraction involves retrieving data from diverse sources such as CRM systems, ERP software, or external APIs. Transformation includes cleaning and restructuring data to ensure consistency, such as standardizing date formats or correcting anomalies. Loading involves transferring the processed data into a target storage system, ready for analysis or reporting. ETL workflows automate data handling, enabling timely and reliable data integration across organizational systems.
How it works
The process begins with data extraction, where data is gathered from multiple sources. For example, a retail company might extract sales data from an online store, in-store POS systems, and logistics partners. These sources often use different formats and interfaces, necessitating connectors or APIs for consistent retrieval.
Once extracted, data moves into the transformation phase. Here, data cleaning is key—removing duplicates, correcting errors, and handling missing values. Standardization, such as converting all date fields to ISO 8601 format (YYYY-MM-DD), improves consistency. Complex transformations might include aggregating sales by regions or calculating customer lifetime value. This phase ensures data quality and prepares it for analysis.
Following transformation, data is loaded into a data warehouse or data lake. Data warehouses are structured environments optimized for online analytical processing (OLAP). Data lakes, on the other hand, store raw data in its native format, offering flexibility. The load process involves inserting, updating, or appending data, often using dedicated tools like Apache NiFi, Talend, or custom scripts.
Automation tools, scheduling systems, and monitoring are integral to maintaining reliable ETL pipelines. Companies such as Amazon Web Services and Microsoft Azure provide managed services that facilitate building and managing these workflows, ensuring that data integration remains consistent despite changes in source systems or data volume.
The entire ETL cycle is designed for efficiency and scalability. For instance, a pipeline processing 10 million records per day might complete extraction and transformation within 15 minutes, provided optimized resources and parallel processing are employed. The robustness of ETL processes directly impacts data freshness and accuracy in decision-making environments.
Practical application
Businesses leverage data, databases, and ETL workflows across multiple domains. In marketing, companies analyze customer interactions captured from website logs, email campaigns, and social media platforms. By integrating these data streams, they develop comprehensive customer profiles—leading to targeted outreach and improved conversion rates. For example, a retail chain might integrate data from 25 sources, totaling over 200 million records monthly, allowing detailed segment analysis and campaign optimization.
Financial institutions rely heavily on large-scale databases combined with ETL processes to monitor transactions, detect fraud, and comply with regulations. Banks process millions of daily transactions, extracting relevant data, transforming it into standardized reports, and loading it into compliance systems. Time-sensitive ETL workflows—completing updates in under 30 minutes—are vital to prevent fraudulent activities or regulatory delays.
Healthcare providers utilize data warehouses to consolidate patient records, lab results, and treatment data. ETL pipelines ensure data consistency across different systems like electronic health records (EHR) and medical imaging databases. By integrating structured and unstructured data, providers can analyze treatment outcomes, identify trends, and improve care quality.
Manufacturing firms depend on real-time data collected from sensors and IoT devices on production lines. These data streams are extracted continuously, cleaned, and loaded into central repositories. Advanced analytics then identify bottlenecks or predict equipment failure before it occurs, minimizing downtime and reducing maintenance costs.
Public sector agencies employ data integration for urban planning, transportation management, and emergency response. For example, city governments may amalgamate traffic data, weather reports, and social media feeds to optimize traffic flow in real time. ETL processes automate the consolidation of these diverse data sources, enabling decision-makers to act swiftly based on current insights.
In each case, the efficiency and integrity of data workflows directly influence operational outcomes. Properly designed ETL pipelines facilitate timely insights, support compliance, and enhance overall data quality, empowering organizations to make data-backed decisions confidently.
Common mistakes
One frequent error involves inadequate planning during the design of ETL pipelines. Without considering source system changes or data growth, pipelines may break or become sluggish over time. For example, a project that doesn't account for increasing data volume may face storage bottlenecks within six months.
Failing to implement proper data validation and error handling can lead to inaccurate reporting. An instance is neglecting to flag duplicate records, which skews analytics results. Over time, these errors compound, reducing data credibility and risking poor decision-making.
Over-optimizing for speed at the expense of data quality is another common mistake. Rushing transformation processes without validation steps might lead to incorrect data being loaded into systems. It is essential to balance processing speed with verification, especially in sectors like finance or healthcare where accuracy is critical.
Another issue arises from fragmented or inconsistent documentation of data sources and workflows. Lack of clear records hampers troubleshooting and onboarding, leading to delays and errors. Maintaining thorough documentation of pipeline configurations and data schemas mitigates this problem.
Expert recommendations
Design ETL workflows with scalability in mind. As data volume grows, pipelines should adapt without significant overhauls. Using modular architectures allows components to be upgraded independently and supports parallel processing where possible. Companies like Snowflake and Google BigQuery emphasize scalable, cloud-based ETL frameworks that adjust dynamically to workload size.
Prioritize data quality at every step. Implement validation checks during extraction and transformation. Automated testing of data samples can catch issues early, preventing flawed data from contaminating large datasets. Tools such as Great Expectations or Apache Griffin facilitate this process.
Leverage automation and continuous monitoring. Scheduling ETL jobs outside peak business hours reduces system load. Monitoring dashboards, alert systems, and logging enable prompt detection of failures or anomalies, ensuring high pipeline availability. Building redundancy into workflows minimizes downtime.
Maintain comprehensive documentation and metadata management. Clear records of data sources, transformation logic, and pipeline versions improve maintainability and onboarding. Using data catalog tools like Apache Atlas or Collibra can assist in keeping this information accessible and up-to-date.
Conclusion
Understanding how data, databases, and ETL processes interconnect forms the foundation of effective data management. Their proper implementation enhances data quality, ensures operational efficiency, and enables advanced analytics. As organizations confront increasing data volumes, the importance of scalable, reliable pipelines only grows.
Organizations that invest in solid design principles, validation, and automation stand to gain the most from their data assets. Clear workflows and attention to detail are crucial for extracting meaningful insights. Ultimately, data management remains a vital component of any data-centric enterprise strategy.